LLM spend monitoring for AI teams
Know your token burn every morning — before it becomes the bill.
TokenBurn watches your OpenAI, Anthropic and self-hosted OpenClaw spend continuously and tells you, in plain language, what changed, why, and who should care. Spot the ember before it becomes the fire.
5-minute setup · Key used only for read-only endpoints · No credit card
$1,284
+18% vs yesterday
claude-opus-5 · prod-assistant
+41% in 3 days
The problem
LLM waste doesn't start as an explosion. It starts as an ember.
A runaway agent loop. A prompt that never hits the cache. An eval job pointed at your most expensive model. A forgotten API key still burning in someone's side project. Nobody notices until the invoice arrives — and by then, you're arguing about a surprise bill instead of shipping.
Most usage pages are dashboards. Dashboards need to be remembered. Engineers don't have time to remember. TokenBurn inverts this — it watches for you, and shows up in your morning routine only when something actually changed.
How it works
From zero to daily clarity in five minutes.
No SDK to wire in. No proxy in front of your requests. Just an Admin API key that we only use against the read-only usage and cost endpoints. Self-hosted OpenClaw? Point TokenBurn at your gateway and see every agent's burn plus your Claude/OpenAI plan usage windows.
- 01
Sign in
Email or Google. One click, nothing to install on your side.
- 02
Paste an Admin API key
Create an Admin API key in OpenAI or Anthropic — or, on Anthropic, a personal or service-account key with no workspace scope, no admin role needed — and paste it once. Self-hosted OpenClaw? Paste your gateway URL and token instead. Secrets are encrypted at rest and only ever used for read-only usage and cost endpoints.
- 03
Pick projects, workspaces or agents
Watch every project, workspace or OpenClaw agent, or only the ones you care about. Change it any time.
- 04
Get your morning burn report
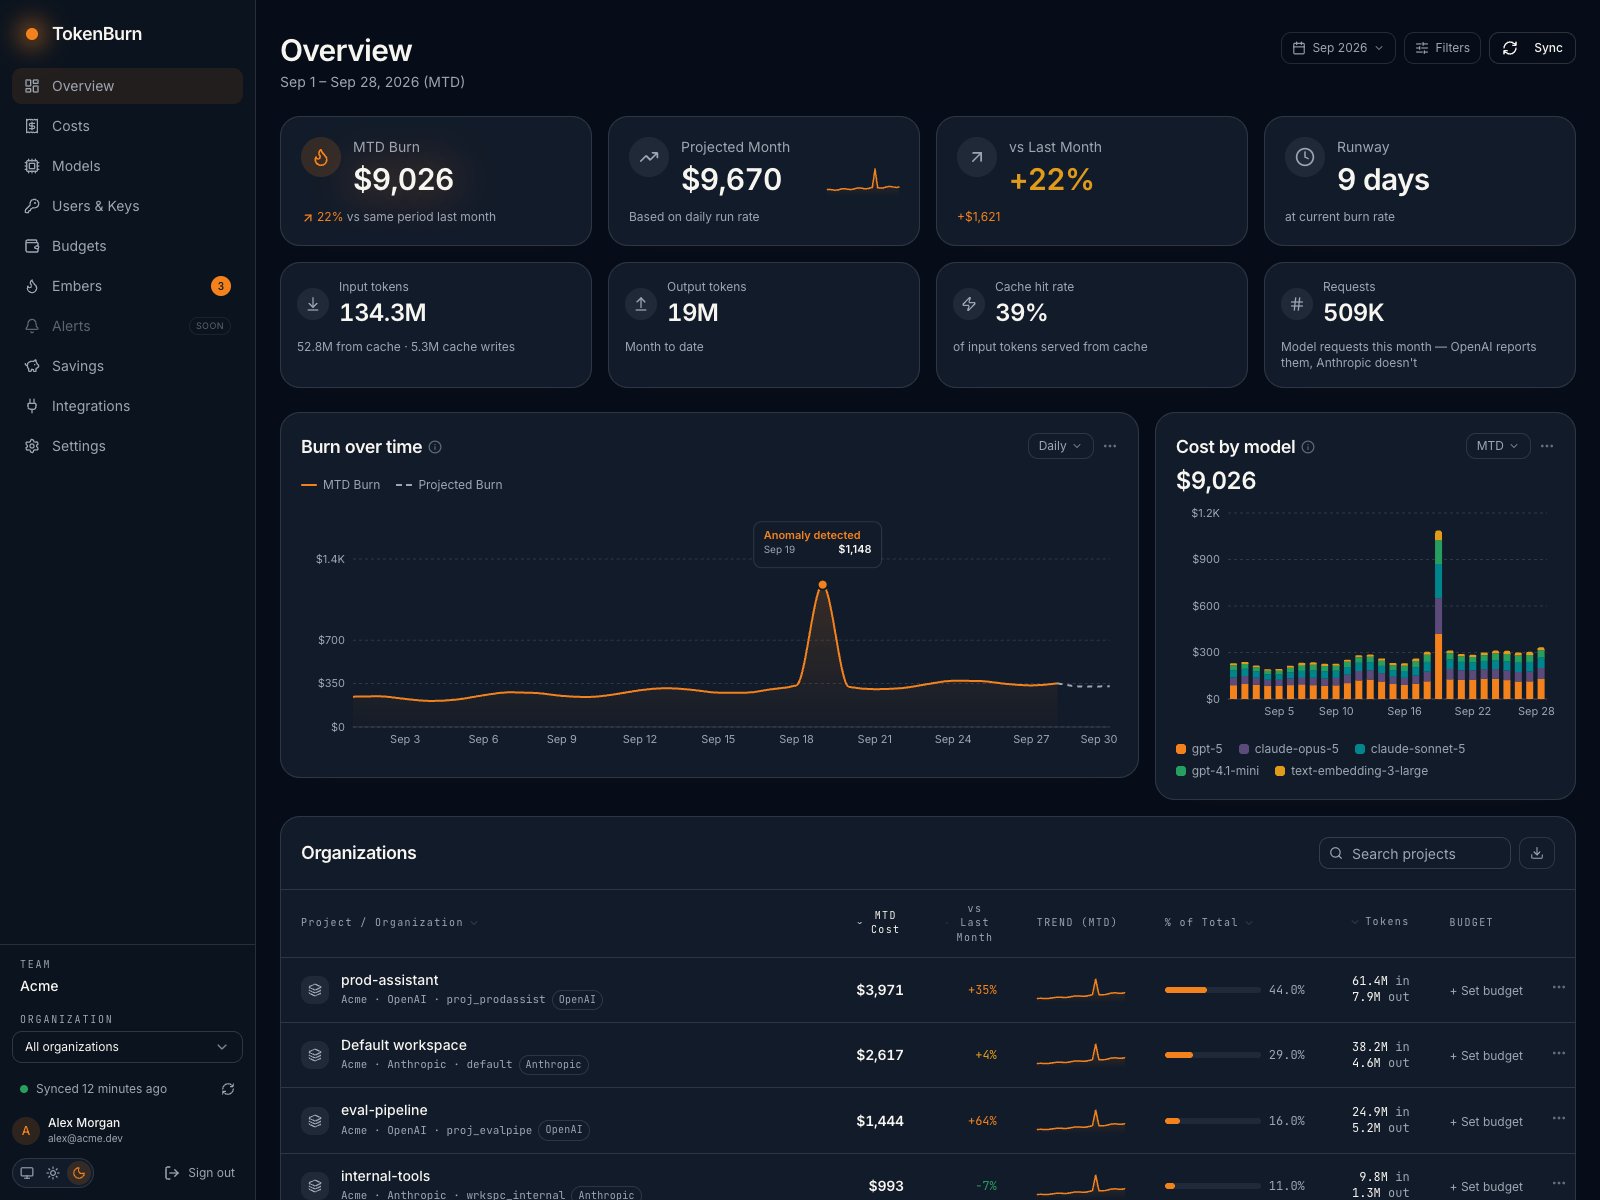
MTD spend, projected month-end, tokens in and out, top movers, and the embers we've spotted — all before your first coffee.
Features
Everything you'd build yourself — if you had time.
Ember detection
We surface the top movers in the last 7 days with plain-English explanations. "claude-opus-5 in prod-assistant is up 41% — cache hit rate fell off a cliff on Tuesday."
Cost by project & model
See every organization broken down by project or workspace, model, and line item — input, output, cached input, cache write. Drill into any spike in two clicks.
Users & API keys
Know who is burning. Tokens and cost per user and per API key — reported by OpenAI, estimated from list prices for Anthropic — so a runaway loop has a name attached before lunch.
Runway, not just spend
Enter your monthly budget and we show days of runway alongside MTD burn. Founders think in runway — we do too.
Morning digest
One email every morning with exactly what changed and why. No dashboards to remember.
Encrypted, read-only use, deletable
Your keys are encrypted at rest and never shown again — not even to you. We only call read-only usage and cost endpoints, and you can delete a key any time.
The metaphor
LLM spend is burn rate. Treat it that way.
Founders track burn because it decides how long they survive. AI teams should treat token spend the same way — as a single number that changes every hour, and that someone must actually watch.
TokenBurn is that someone.
Cache discount left on the table
up to 90%
Cached input vs. full price
Time to detect a runaway loop
Days
Checking usage pages by hand
Time to detect with TokenBurn
< 24h
Daily digest + ember alerts
Setup time
~5 min
Sign in + paste an Admin key
Illustrative figures — your numbers depend on your traffic and models.
Pricing
Free during beta. Flat rates when we launch.
No percent-of-savings fees, ever. Your savings should be your savings.
Solo
Free
in beta
- 1 organization
- Daily digest
- Ember detection
- Email support
Team
Popular$99
/ month (later)
- Up to 10 organizations
- Slack + email digests
- Multi-user access
- Priority support
Scale
Talk to us
volume + SSO
- Unlimited organizations
- SAML SSO
- Custom alerts & webhooks
- Dedicated Slack channel
Get your first burn report tomorrow morning.
Sign in, paste an Admin API key, and wake up to clarity.